What needed to work better?
Voice-enabled products need a consistent way to create speech without repeatedly uploading the same reference material for each request.
Voice Cloning & TTS API
A FastAPI service built around Chatterbox TTS for text-to-speech generation and voice personalisation from reference audio.
Developers building voice assistants, narration, and audio tools
Voice-enabled products need a consistent way to create speech without repeatedly uploading the same reference material for each request.
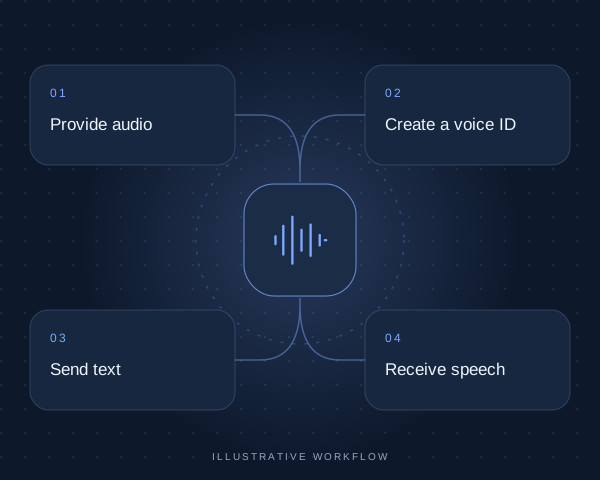
A reference audio sample establishes a reusable voice identity. The API then combines that voice with new text to produce speech, with controls for expressive delivery.
Core capabilities that turn the idea into a practical product.
Create a voice identity from a supplied audio sample.
Generate additional speech using the stored voice reference.
Expose speech generation through a FastAPI backend.
Tune supported model parameters for speech delivery.
Select a step to see how the project moves from input to outcome.
Supply a reference sample for the intended voice.
Store the reference for repeated use.
Submit new content and supported generation settings.
Return generated audio to the calling application.
Explore the project visual in more detail.
The stack behind this project and its connected workflow.
Tell us about your users, your current systems, and the work you want to make easier.