What needed to work better?
Useful knowledge often lives in long videos and separate documents. Finding the relevant passage manually interrupts research and learning.
YouTube + Document Chatbot
A conversational assistant that retrieves relevant information from YouTube transcripts and uploaded files before generating an answer.
People researching video and document collections
Useful knowledge often lives in long videos and separate documents. Finding the relevant passage manually interrupts research and learning.
The application ingests transcripts and document text, builds a searchable vector index, and retrieves context from both sources for the answer-generation step.
Core capabilities that turn the idea into a practical product.
Turn available video transcripts into searchable material.
Work with PDF, DOCX, and TXT content.
Use embeddings and FAISS to find relevant passages.
Provide retrieved context to the conversational model.
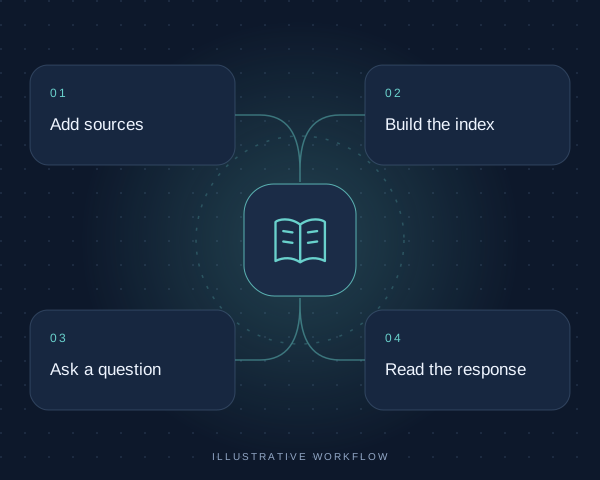
Select a step to see how the project moves from input to outcome.
Supply a video link or supported document.
Prepare text and embeddings for retrieval.
Search the available material for relevant context.
Receive an answer based on the retrieved passages.
Explore the project visual in more detail.
The stack behind this project and its connected workflow.
Tell us about your users, your current systems, and the work you want to make easier.